

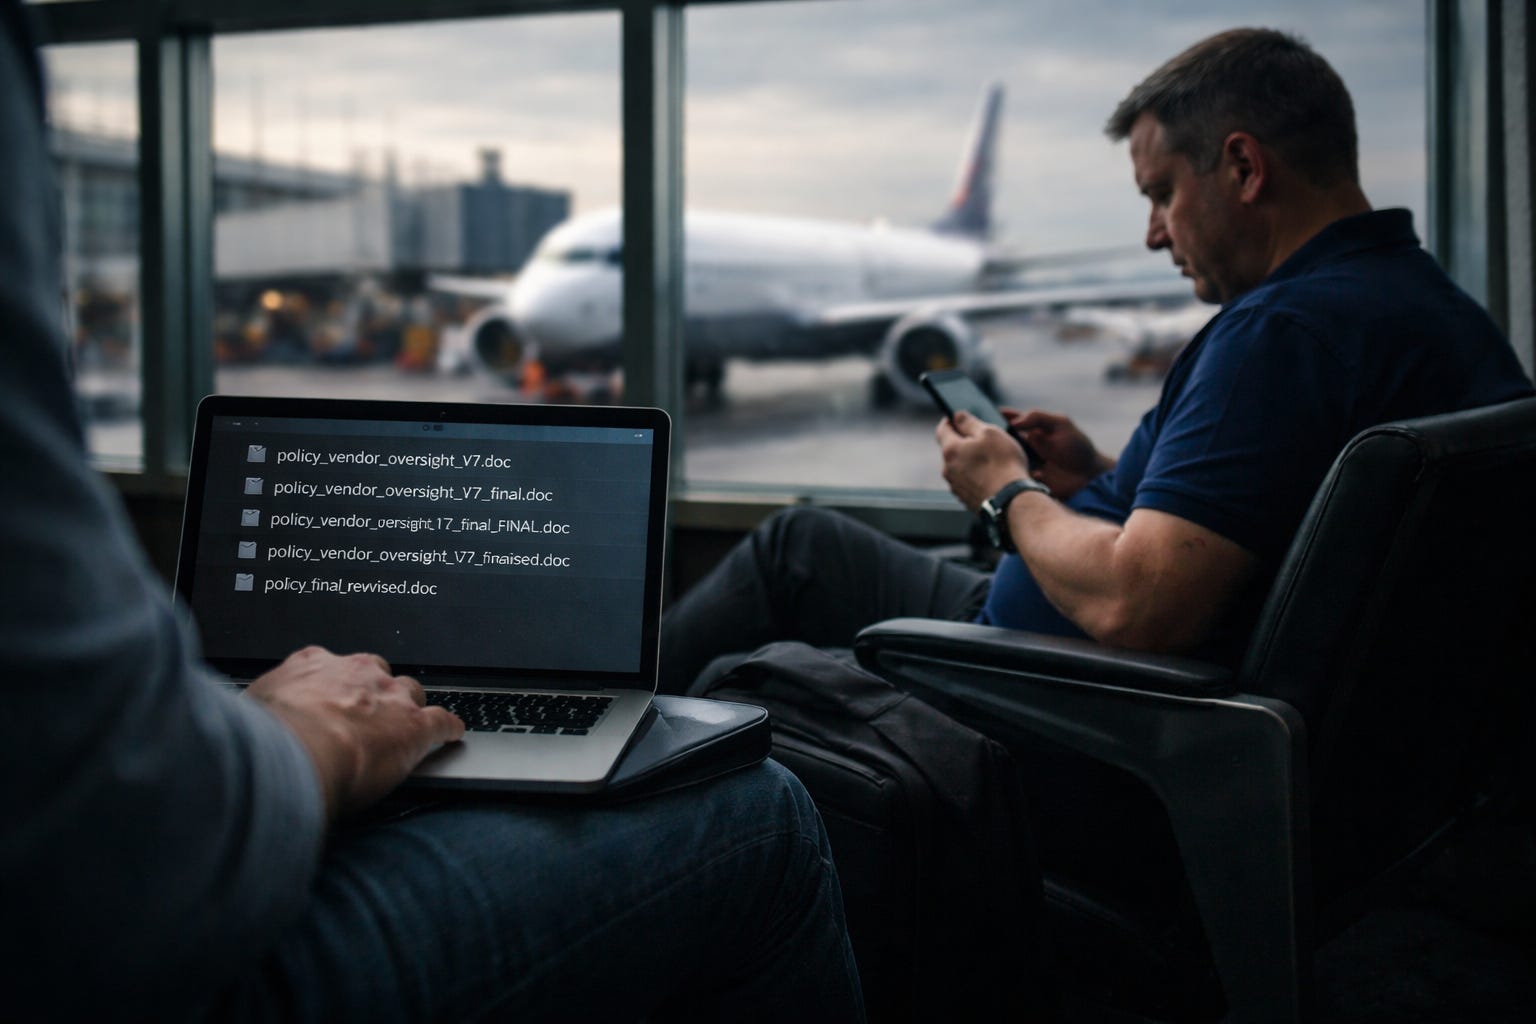
It started at a gate at BOS heading to Austin-Bergstrom.
Flight delayed. Of course. Gate packed. Construction. The guy sitting next to me in the company-logo polo works in insurance.
You know how these conversations go. Weather in Boston. Humidity in Austin. March Madness. Thirty minutes later we’re knee deep in the weeds…state-by-state regulatory fragmentation, explainability requirements, vendor oversight rules. How his team was rewriting the same core policy document for every jurisdiction it touched.
All. By. Hand.
I asked him one question.
“What if the system already knew the template?”
No deck. No capabilities overview. No “let me tell you what we do.” One question. He put his phone down.
I should be transparent about something here. I hadn’t walked into that airport as a compliance AI expert. (Yes, I work in regulated verticals like pharma, finance, security, but I’m just now building AI Systems for these compliance heavy industries.) I’d been reading up on RAG systems the week before - a friend in HR/talent acquisition was wrestling with a documentation problem that sounded a lot like an architecture problem, and I was trying to figure out whether there was a custom build worth recommending (and then recommending that I build it). So, I went head first down the rabbit hole. Drink me.
That’s actually the Columbo move I didn’t know I was making. I wasn’t trying to impress him. I had a Bloody Mary (or three) at Walburgers and my salesguy-finger-pistols were stowed. Safety first. I just asked the question that had legitimately been rattling around my head from the recent research I’d been doing.
The person talking is giving away information. The person asking one good question is collecting leverage.
By the time we landed, golf-polo greenlit an AI systems diagnostic via email. (Thanks for the free wifi, JetBlue!) And I hadn’t even checked into the hotel in Austin. Alright, alright, alright.
The thing he was describing isn’t an insurance problem.
It’s a compliance problem. An operations problem. A “we have the same document in twenty different versions and they all live in someone’s head OMG is thing on” problem.
And it shows up everywhere.
Pharmaceutical teams rewriting the same trial documentation for different regulatory bodies - and they’re own legal. Financial services firms manually reconciling reporting requirements across jurisdictions - then filing it away in its own separate folder never to be compared for efficiencies. Healthcare systems producing the same core document in a dozen different formats because a dozen different stakeholders need a dozen different things.
The work isn’t strategic. It’s pattern-matching at scale. It’s pulling the right language, checking against the right standard, formatting to the right template. And somewhere in your organization right now, a smart smartie of a person with a loaded hourly cost is doing it by hand. By. Hand. Because that’s how it’s always been done. If you’re partner a law firm…congrats you just made Q1 bonus. The rest of us are burned out data researchers with a high propensity to make inventible, totally understandable but undeniably preventable mistakes.
Here’s what makes all this urgent and not just plain old annoying: the compliance landscape is accelerating faster than most teams realize. As of early 2025, 24 states had adopted the NAIC’s AI Model Bulletin — each with governance, documentation, and explainability requirements that insurers must demonstrate, not just claim. New York’s DFS Circular Letter 2024-7 goes further, requiring insurers to maintain explanatory documentation, allow regulatory review of vendor AI tools, and document how inputs lead to specific outputs.
The patchwork isn’t simplifying. It’s compounding. And the teams manually reconciling it are falling further behind every quarter.
SFW?
The system could already know the template.
Most organizations just haven’t built it yet.
Why the question worked.
I didn’t ask polo guy (Marco? Marco.) about AI. I didn’t pitch RAG systems by name. I asked one question that reframed his problem from a people problem into an architecture problem. SFW?
You don’t need better people, you need a better system.
Smart people can do amazing things with the right tools. That’s the shift. Feel it?
Most enterprise AI conversations stall because they start with capability.
Here’s what the technology can do. Here’s our platform. Here’s our integration roadmap. (They should read my book, just sayin… #SFWLife)
The technology becomes the subject, and the human across the table becomes an evaluator.
Start with the template nobody automated, and the conversation changes completely. Now the technology is incidental. The subject is their problem. Now you’re a thinking partner, not a vendor.
So what does “The system already knows the template” actually mean?
The short version: RAG - Retrieval-Augmented Generation - is an architecture that lets an AI system draw from a curated knowledge base before it generates anything. Think of it as NotebookLM all hopped up on creatine, peptides, and nootropics, with access to your entire regulatory compliance library before it touches a single output.
Most people's experience with AI is a general-purpose model generating from what it absorbed during training. Ask it about compliance documentation and it'll produce something that sounds plausible.
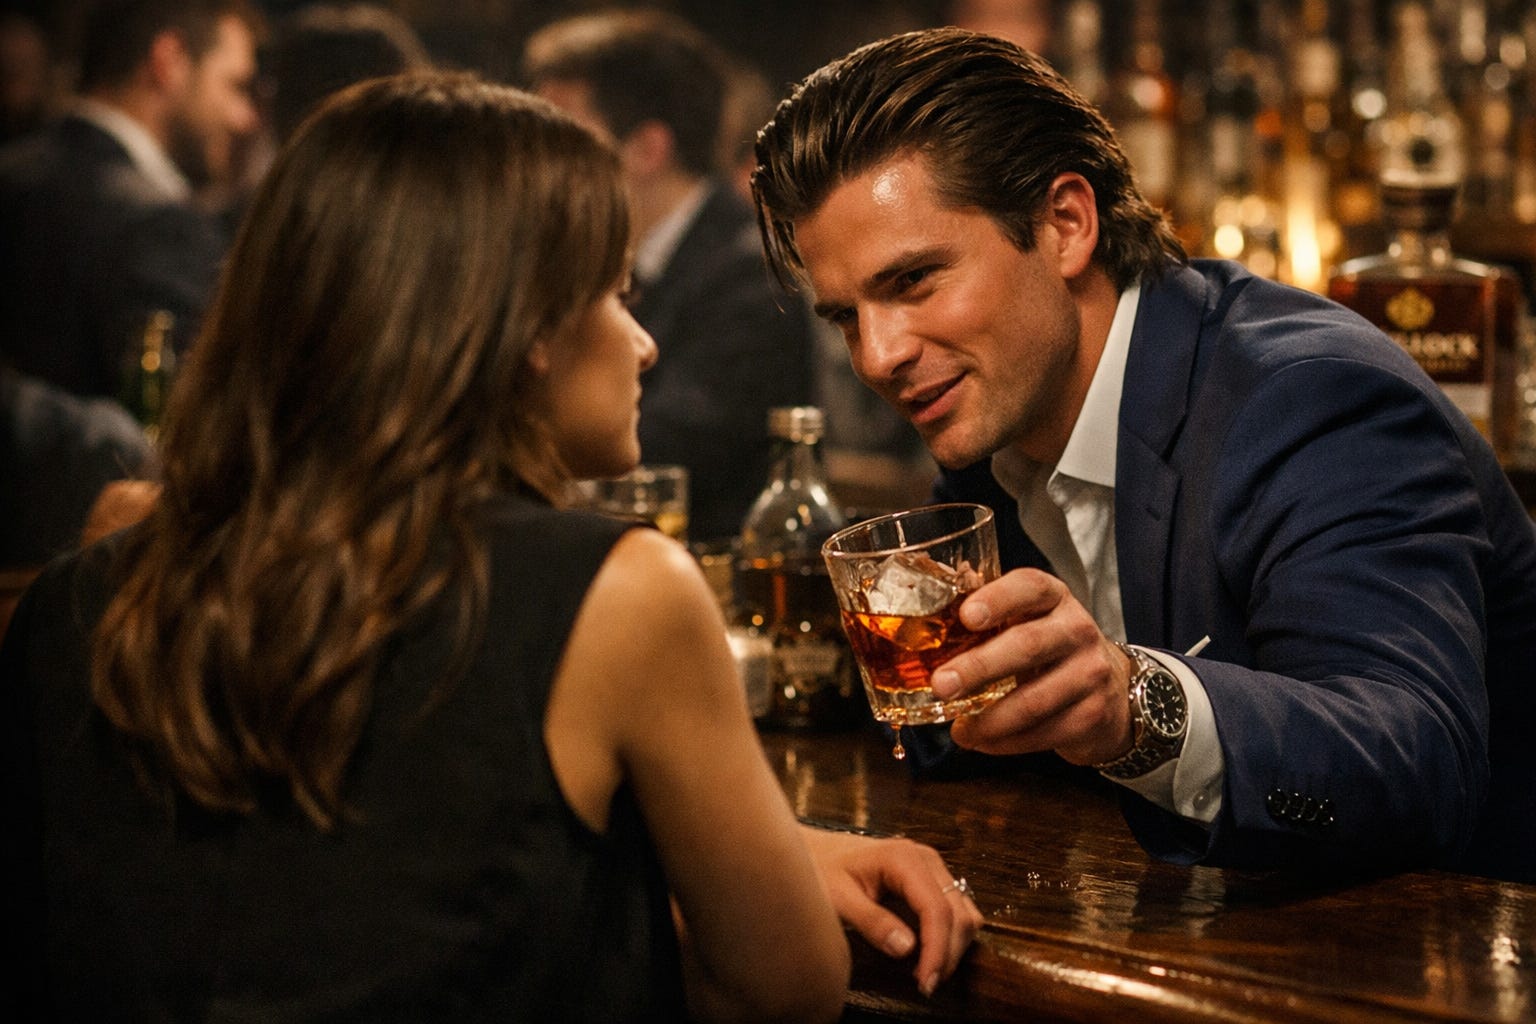
Which is exactly the problem. Generic AI vs a RAG system that knows the template is the difference between a finance bro splashing his Hillrock Old Fashioned on your toes at the bar and a Beltway Chief Compliance Officer who helped write the actual filing (the regulator already signed off on) over noontime martinis at Old Ebbitt Grill. One can get you an inside line at the new crypto bruh, the other keeps you and your lawyer out of court. Plausible-sounding compliance documentation that isn't grounded in your specific regulatory environment isn't just not useful — it's an actual liability.
RAG solves this by anchoring generation to your actual sources. When the system cites its work, your team can verify outputs and trace exactly where the language came from. For insurance compliance specifically, that traceability isn’t a feature. It’s a regulatory requirement — the NAIC’s AI Model Bulletin explicitly requires insurers to demonstrate how inputs lead to specific outputs. Your citation layer is your audit trail.
The human in the loop - and there is always a human in the loop - shifts from writer to reviewer. That’s the unlock. Not eliminating the expertise. Relocating it where it is best utilized.
(One honest caveat worth naming: anyone selling you “fully automated compliance” is selling you liability, not a solution. The machine drafts. A qualified human approves. That’s the architecture. Design accordingly.)
What this actually requires.
Three components. Strategic altitude only here; the technical spec is horse of a different color and a different conversation. (Coming Soon!)
A curated knowledge base. This is the foundation and the most underestimated piece of the work. The system is only as good as what you put in. Your actual regulatory templates — not summaries, not interpretations, the source documents — organized by jurisdiction and decision type. This is not a one-time upload. It’s an ongoing curation discipline. Treat it like one.
A retrieval and generation layer with mandatory citation. When a request comes in - “draft a vendor oversight section for a New York underwriting filing” - the system needs to find the relevant regulatory language, match it to your existing documentation, and show its work. Which rule, from which source, from which jurisdiction. That output trail is what your reviewers check. Get the retrieval wrong and the output looks authoritative and is completely wrong. Invest in this layer proportionally.
A maintenance protocol. Regulations change. Your knowledge base needs to stay current - through automated updates, periodic reviews, or both. AWS identifies this as the most common operational challenge: documents and their indexed representations need ongoing maintenance as source material evolves. This is the piece most proofs-of-concept skip and most production deployments eventually regret. Build the update process before you build the system.
The SFW for anyone running an operation with compliance overhead.
Your team is not drowning because they lack expertise.
They’re drowning because they’re applying expertise to work the system could do; and that expertise gets consumed by production when it should be concentrated on judgment.
That’s the real cost. Not the hours. The dilution.
A well-built system doesn’t make your compliance team redundant. It makes them dangerous in the best possible way; freed up to catch the things that require actual judgment instead of burning that judgment on the fifteenth version of the same document.
Polo shirt guy figured this out somewhere over Tennessee. When we touched down in Austin, he wasn’t thinking about his flight delay. He was thinking about how many people on his team were still rewriting templates by hand.
That’s the question.
What if the system already knew the template?
If that lands for someone in your organization the same way it landed for him, you have your answer.
Your move.
If you’re running an operation where your smartest people are still doing pattern-matching by hand - compliance, reporting, documentation, research - I’d genuinely like to hear about it. Not to pitch. To understand. DM me or reply here. First conversation is just conversation.
Francis Skipper is the founder of Points South Consulting and creator of the SFW:Unlocked framework. He works with enterprise teams and agency leaders on AI systems that replace manual production with strategic capacity.
Sources: NAIC Model Bulletin on the Use of Artificial Intelligence Systems by Insurers (December 2023, 24 states adopted as of March 2025); NY DFS Insurance Circular Letter No. 2024-7 (July 2024); IBM, “What is Retrieval-Augmented Generation,” 2025; AWS, “What is RAG? Retrieval-Augmented Generation AI Explained,” 2025.